ScenarioControl: Vision-Language Controllable Vectorized Latent Scenario Generation
Lili Gao*, Yanbo Xu*, William Koch*, Samuele Ruffino, Luke Rowe, Behdad Chalaki, Dmitriy Rivkin, Julian Ost, Roger Girgis, Mario Bijelic, Felix Heide
ECCV 2026
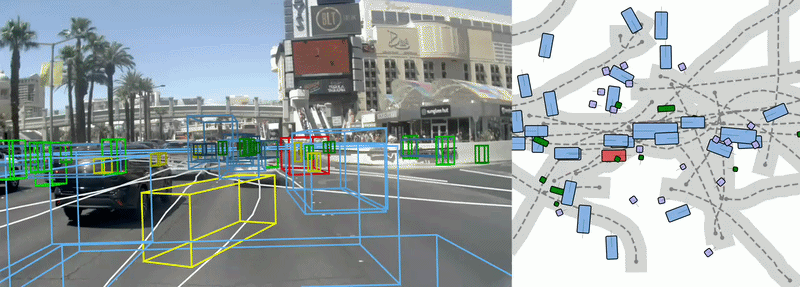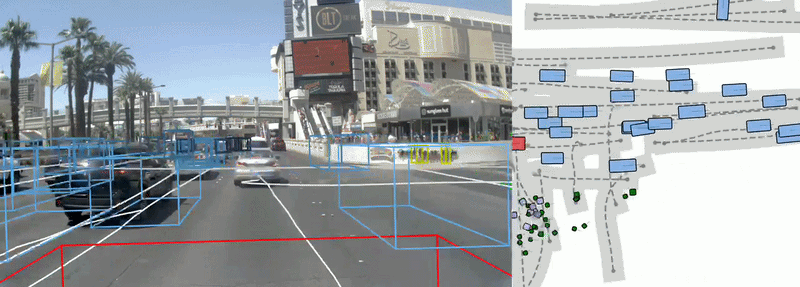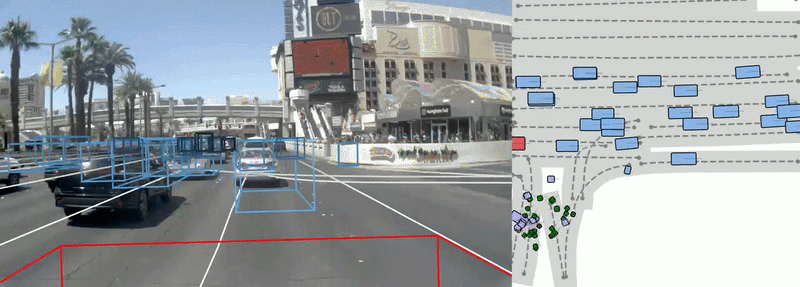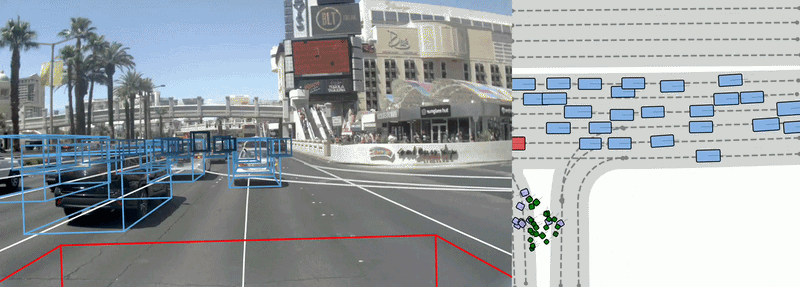
We introduce ScenarioControl, the first vision-language control mechanism for learned driving scenario generation. Given a text prompt or an input image, Scenario-Control synthesizes diverse, realistic 3D scenario…
We introduce ScenarioControl, the first vision-language control mechanism for learned driving scenario generation. Given a text prompt or an input image, Scenario-Control synthesizes diverse, realistic 3D scenario rollouts - including map, 3D boxes of reactive actors over time, pedestrians, driving infrastructure, and ego camera observations. The method generates scenes in a vectorized latent space that represents road structure and dynamic agents jointly. To connect multimodal control with sparse vectorized scene elements, we propose a cross-global control mechanism that integrates crossattention with a lightweight global-context branch, enabling fine-grained control over road layout and traffic conditions while preserving realism. The method produces temporally consistent scenario rollouts from the perspectives different actors in the scene, supporting long-horizon continuation of driving scenarios. To facilitate training and evaluation, we release a dataset with text annotations aligned to vectorized map structures. Extensive experiments validate that the control adherence and fidelity of ScenarioControl compare favorable to all tested methods across all experiments.